How to Get More Performance Out of the Server You Already Have
Dedicated servers outperform other hosting types on raw capability and isolation — and they cost accordingly. That premium is exactly why the question keeps coming up: once the hardware is paid for, how do you make sure you're actually getting everything it can deliver?
The answer isn't to buy more of it. It's to stop wasting what's already there. Three approaches account for most of the gain, and none of them requires new hardware.
1. Virtualisation: stop buying capacity you don't use
If you're running several projects, the instinct is to buy a server per project. That gets expensive fast — and much of the capacity sits idle most of the time, because no single project needs a dedicated machine around the clock.
Virtualisation solves this by dividing one physical server into multiple isolated virtual environments. Each environment can run its own operating system and its own applications, sized to what that particular project actually requires.
Two things follow from that:
- Utilisation goes up without new spend. The hardware you already own gets shared across workloads rather than reserved for one.
- Isolation is preserved. Each virtual instance is separated from the others, so projects don't interfere with each other's configuration.
For organisations with several concurrent projects and uneven demand, this is usually the single largest efficiency gain available — and it's a matter of configuration, not procurement.
2. Monitoring tools: catch problems before they become incidents
A good management toolset does two jobs: it makes the people running the server more effective, and it prevents issues from escalating into downtime.
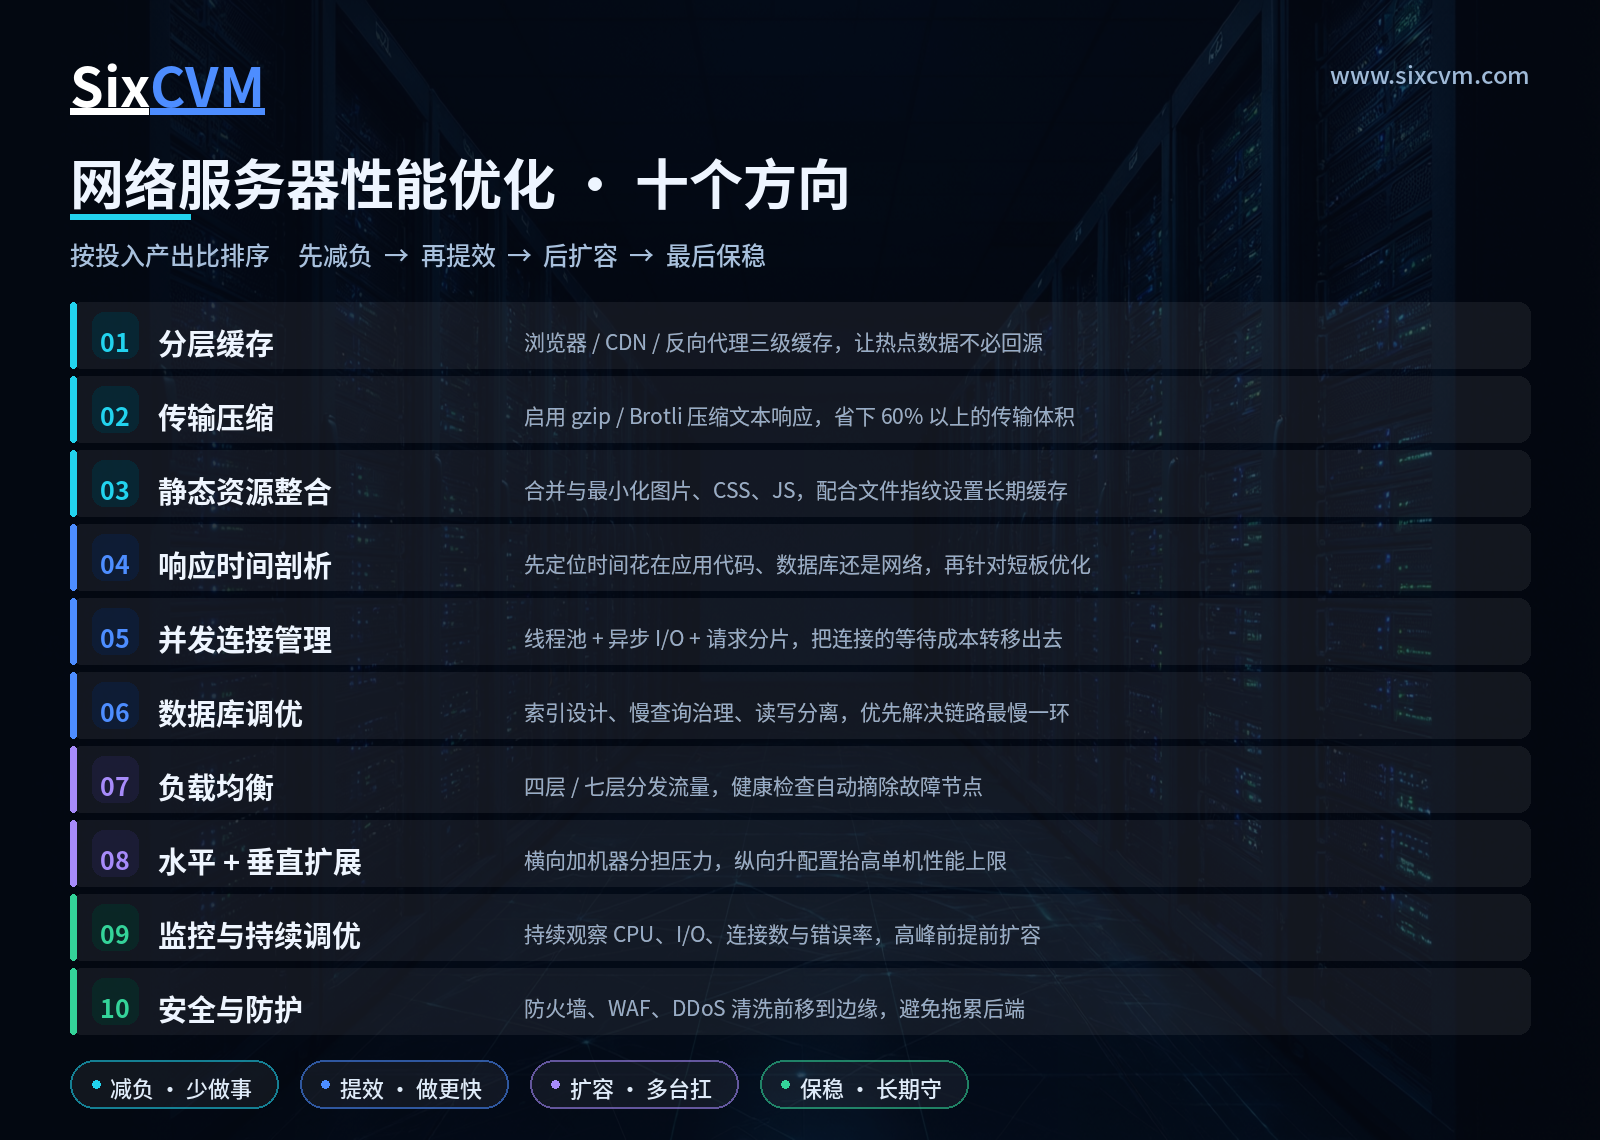
Visibility first. Administrators can watch CPU and memory utilisation continuously, review fault reports, and set thresholds that trigger automatic alerts when something drifts out of range. The value here isn't the data itself — it's the lead time. A memory leak or a runaway process caught at 60% utilisation is an inconvenience; the same problem discovered when the server is unresponsive is an outage.
Then automation. Beyond observation, tools can plan workload distribution based on the server's current condition and the number of active projects. Rather than manually deciding which service goes where, the tooling balances the load — which means resources get used closer to their actual capacity instead of being kept idle as a safety margin.
The compounding effect is what matters: fewer surprises, more uptime, and staff time redirected from firefighting to work that earns.
3. Right-sizing the configuration: remove the bottleneck
Here's a pattern worth noticing. Many servers underperform not because they're overloaded, but because the configuration around them is outdated.
Storage I/O and CPU are the usual constraints. If the disks can't feed data fast enough, or the processor is generations behind, applications queue up waiting — and the machine looks slow even though it isn't saturated. The hardware isn't the problem; the specification is.
That's why refreshing the configuration is a genuine performance measure, not just maintenance. Moving to current storage technology and a modern CPU generation removes the bottleneck that was capping everything else. In cloud environments this is often as simple as selecting a different instance type — no migration project required.
Summary
| Approach | What it fixes | Why it works |
|---|---|---|
| Virtualisation | Idle capacity on underused hardware | Shares one machine across isolated environments sized to each project |
| Monitoring tools | Problems discovered too late; manual load decisions | Alerts catch drift early; automation balances workloads |
| Configuration refresh | Storage and CPU bottlenecks | Removes the constraint that caps everything upstream |
The Bottom Line
Improving server performance splits into two very different activities. You can add resources — buy a bigger machine, upgrade the hardware. Or you can use the resources you have more completely.
The second path is cheaper, faster to execute, and usually where the real waste is hiding. Virtualise to stop paying for idle capacity, monitor so that problems surface early rather than at 3 a.m., and refresh the configuration when storage or CPU has become the ceiling.
Do those three and you'll typically find you don't need the upgrade you were about to buy.
About SixCVM
Founded in 2020, SixCVM serves 10,000+ enterprise customers with Cloud Servers (VPS), GPU Servers, Dedicated Servers, Bare Metal Servers and Domain Registration. Nodes span seven locations — Hong Kong, the United States, Japan, Korea, Taiwan, Singapore and Vietnam — running on NVMe high-speed storage and a high-performance, stable network with CN2 GIA routing. The platform supports instant provisioning and elastic scaling, backed by 24/7 technical support.
CPU, memory, disk and bandwidth can be combined to match your actual workload, and upgrades can be applied online without downtime — so right-sizing isn't a one-time decision you have to get perfectly right on day one.